This was the second homework of Carnegie Mellon’s 11-785 Introduction to Deep Learning in Spring 2025. The real task is face verification: given two face images, decide whether they show the same person, including people the model has never seen. The trick is that you never train on that task directly. You train a classifier over thousands of known identities, throw the classifier away, and keep what it learned to see.
Because this is course work, this page describes the design, the experiments and what I learned, not the implementation itself.
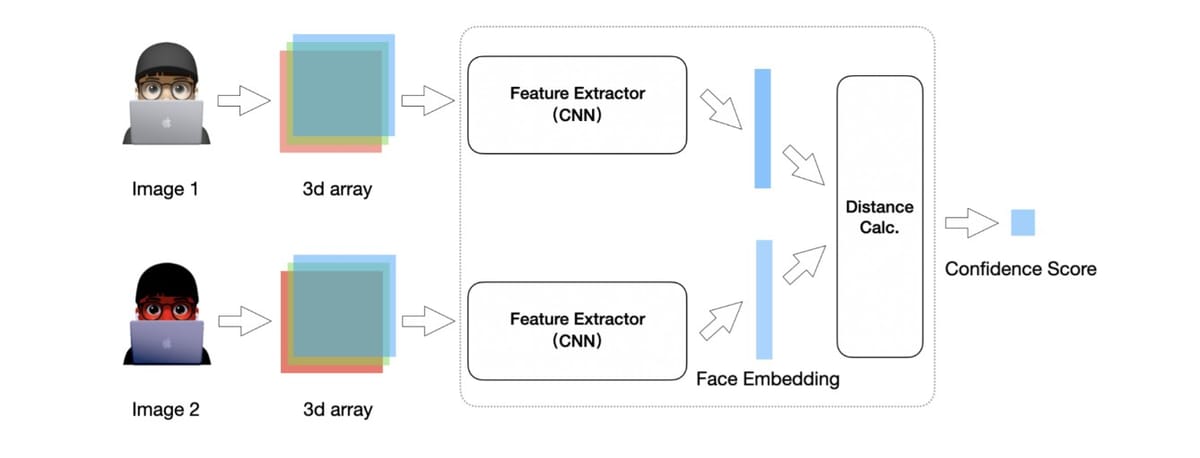
Classification as a Means to an End
The training set is a subset of VGGFace2 with 8,631 identities, with a wide range of poses, ages, lighting and backgrounds. A CNN trained to tell those identities apart has to build an internal representation of a face that captures identity and ignores everything else. The last layer before the classifier is that representation, an embedding.
At verification time, both images go through the network, their embeddings are normalized to unit length, and the cosine similarity between them becomes the score. Two photos of the same person should point in nearly the same direction, and two different people should not. Because nothing in this step depends on the 8,631 training classes, it works for faces outside the training set. This is the difference between closed-set classification and open-set verification, and it is why validation is scored on verification pairs, not on classification accuracy alone.
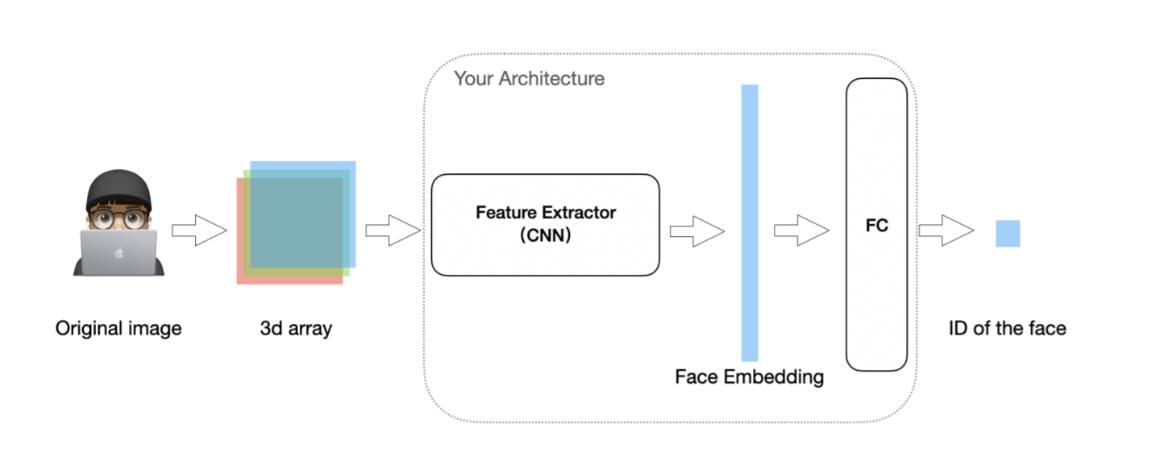
The Network
My final model was a compact residual CNN for 112 by 112 face crops:
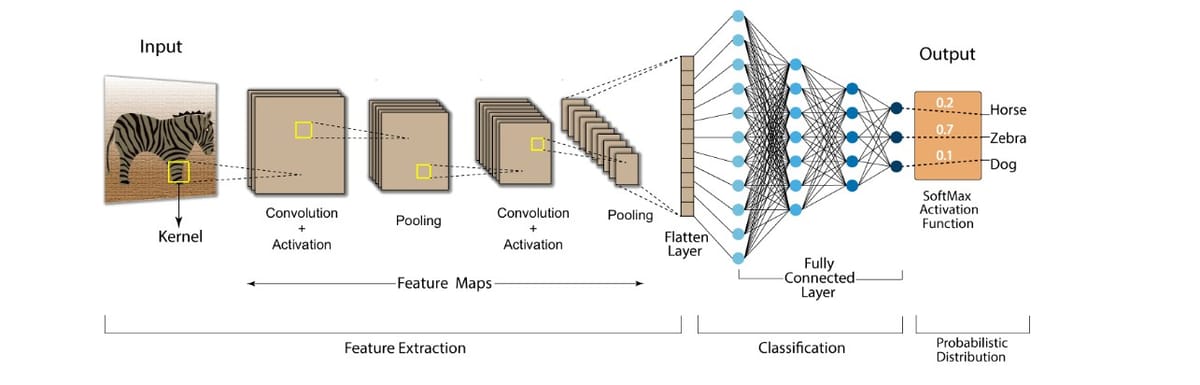
- Stem: a stride-2 convolution with batch normalization and ReLU, followed by max pooling, to bring the resolution down quickly.
- Three residual blocks widening from 64 to 128, 256 and 512 channels. Each block is two 3 by 3 convolutions with batch normalization, plus a 1 by 1 convolution on the shortcut to match channels and stride. The skip connections are what let the gradient reach the early layers cleanly.
- Squeeze-and-excitation on the last block. It pools each of the 512 channels down to a single number, passes those through a small bottleneck (512 to 32 and back), and uses the result to reweight the channels. In effect, the network learns which feature channels matter most for each image.
- Embedding head: global average pooling, dropout of 0.2, and a 512-wide linear layer with batch normalization. That 512-dimensional vector is the embedding used for verification. A final linear layer maps it to the 8,631 classes during training only.
Training
- Loss: cross-entropy with label smoothing of 0.1. Smoothing stops the network from becoming overconfident on training identities, which tends to give a better-shaped embedding space.
- Optimizer: Adam with weight decay.
- Augmentation: random horizontal flips, rotations of up to 10 degrees, brightness and contrast jitter, and mild perspective distortion. Each one simulates a nuisance the embedding should ignore: pose, head tilt, lighting and camera angle.
- Mixed precision training on Kaggle GPUs.
Results
I tracked 23 runs in Weights & Biases, measuring classification accuracy on held-out images and verification accuracy on the validation pairs.
| Run | Epochs | Classification (val) | Verification (val) |
|---|---|---|---|
| 1,726-class subset | 20 | 84.4% | 94.4% |
| Full 8,631 classes | 30 | 87.4% | 97.4% |
| Full 8,631 classes | 50 | 89.4% | 97.4% |
| Full 8,631 classes, best | 60 | 89.0% | 97.9% |
A few things stood out:
- More identities beat more epochs. Training on a 1,726-identity subset never got verification above about 95%, while the best long runs on the full set all landed above 97%. A classifier that has to separate more people learns a more general face representation.
- Classification and verification do not move together. The best verification run was not the best classification run. Past a point, getting better at the training identities stopped transferring to new ones.
- Batch size mattered. A batch of 128 worked best. At 64, training was slower and noticeably worse, and a 256 run on the subset fit the training set well but generalized worse.
What I Took Away
The most useful idea from this homework was that the task you train on does not have to be the task you care about. A classification loss over thousands of identities is easy to optimize, and the embedding it produces happens to be exactly what verification needs. It also changed how I read metrics: the number to watch was verification on unseen pairs, and it diverged from training-set classification accuracy surprisingly early.