TinyPointNeXt was my final project for Carnegie Mellon’s 11-785 Introduction to Deep Learning in Spring 2025, with Dylan Leong and Eric Zhao. I led the project concept and the architecture work: designing and implementing the reduced PointNeXt variants and the experiments that compared them. This page is the implementation summary. The full write-up, with the method, datasets and every result, is on the research page: TinyPointNeXt: Lightweight Architecture for Real-Time Human Detection in 3D Point Clouds.
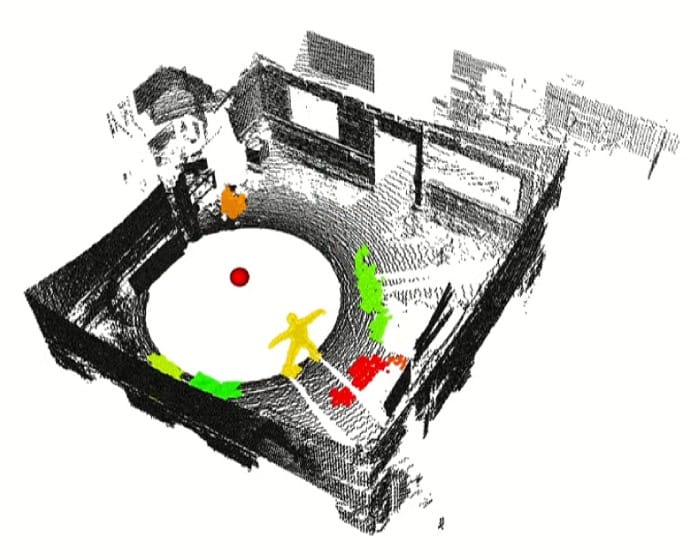
The Problem
A robot moving through a building needs to know which parts of its LiDAR scan are moving, and which of those moving things are people. Dynablox already extracts dynamic clusters from the point cloud, but many of them are false positives: non-human clusters that only look dynamic. We wanted a classifier small and fast enough to sit right after Dynablox and throw those false positives away, so only humans are passed downstream.
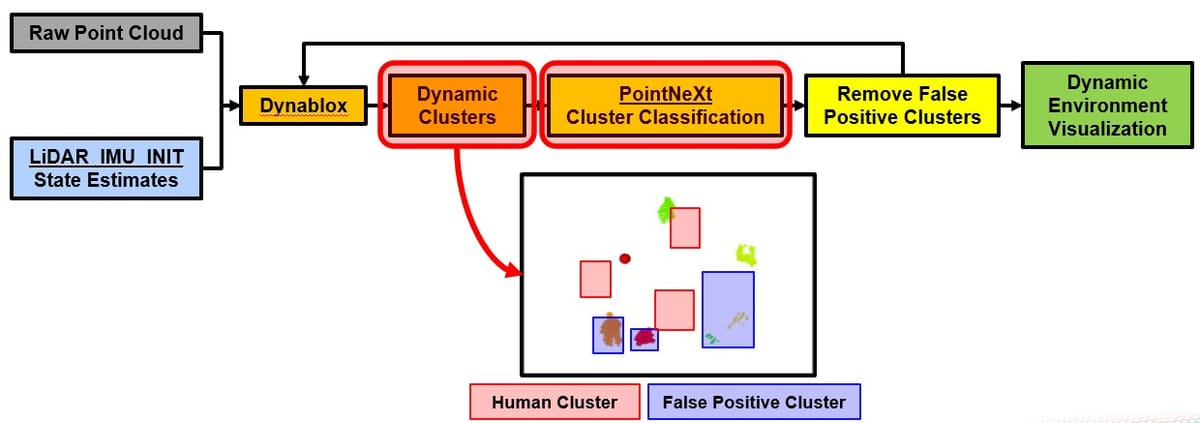
What I Changed in PointNeXt
PointNeXt is a modernized PointNet++: hierarchical set abstraction blocks with inverted residual MLPs, trained with much better augmentation and optimization than the original. Starting from PointNeXt-S as the baseline, I tried three ways of shrinking it:
- Narrower MLPs, cutting the encoder width from 32 to 24 and then 16.
- Fewer set abstraction blocks, from 6 down to 5 and then 4.
- Shallower blocks, with one MLP layer per set abstraction block instead of two.
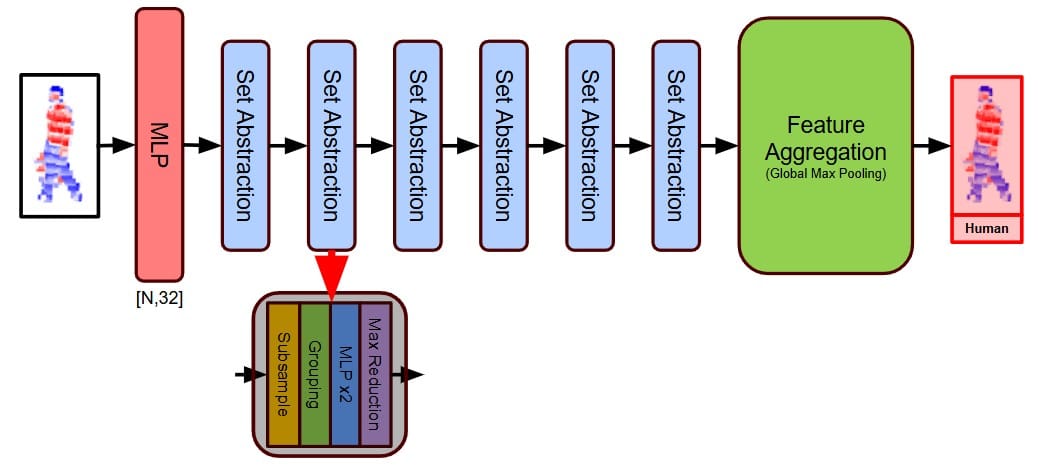
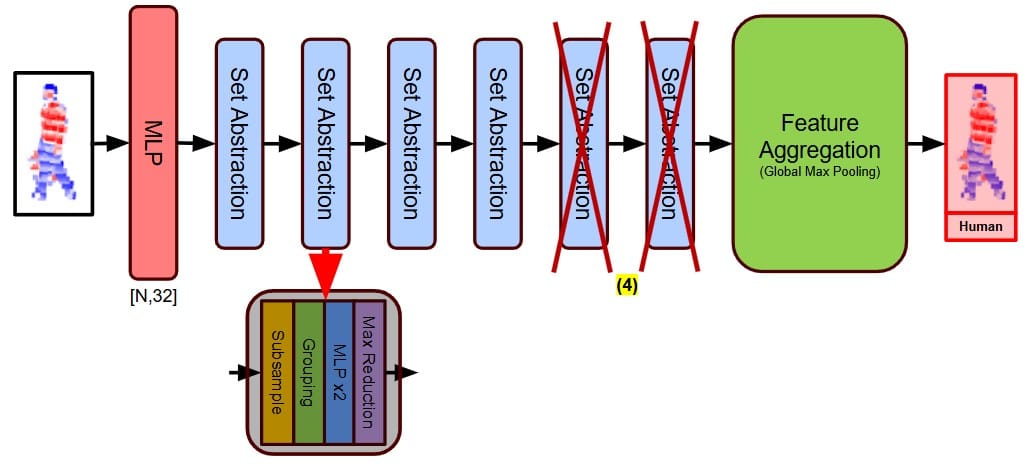
Across encoder width, block count, set abstraction depth and batch sizes, we ran 48 configurations, trained with label-smoothed cross-entropy (alpha 0.2), AdamW at 0.001 and a cosine schedule.
Results
On our custom human detection dataset (4,614 human and 2,397 false positive clusters collected at CMU’s Mill 19), every reduced variant matched or beat the baseline. The best trade-off was the 4-block encoder:
| Metric | 4-block encoder | Change vs. PointNeXt-S |
|---|---|---|
| Overall Accuracy | 93.86% | +1.19% |
| Parameters | 0.2591M | -81% |
| Run time per sample | 2.47 ms | -17% |
That the smaller models did slightly better suggests PointNeXt-S is overparameterized for a two-class cluster problem, and that for this task the training recipe matters more than model size. The research page covers the augmentation study on HeliMOS, the harder Scaife Drone Arena test set, and the per-class results.