This was the fourth and final homework of Carnegie Mellon’s 11-785 Introduction to Deep Learning in Spring 2025, and the one where everything from the semester came together. The assignment had two parts built on the same Transformer library: first a decoder-only language model, then a full encoder-decoder speech recognizer that reuses those pieces and adds an audio encoder in front. Both are built from the attention layers up, not from a pretrained model.
Because this is course work, this page describes the design, the experiments and what I learned, not the implementation itself.
The Building Blocks
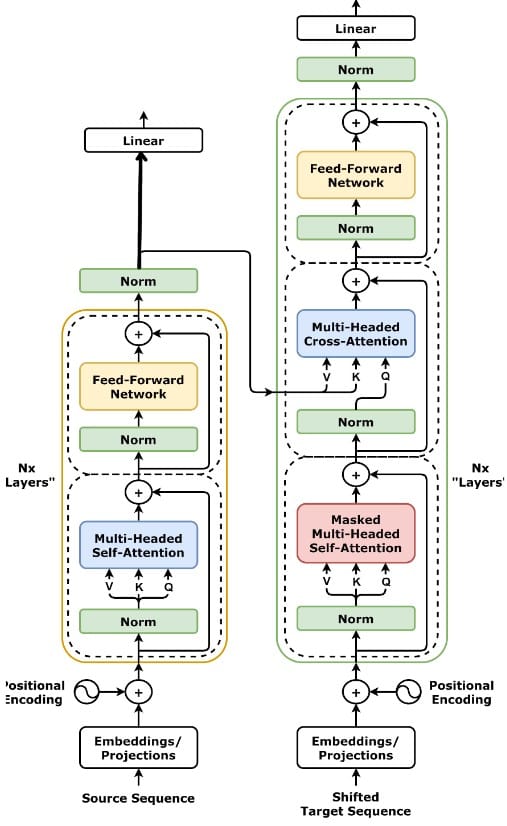
Every layer in both models is a pre-norm Transformer block: layer normalization first, then the sublayer, then a residual connection around it. There are three kinds of sublayer:
- Self-attention, where every position attends to every other position in the same sequence. In the encoder this is unrestricted, since the whole utterance is available at once.
- Masked (causal) self-attention, used in every decoder layer. A causal mask stops position t from attending to anything after t, so the model can be trained on full sequences in parallel and still only ever predicts the next token from the past. A padding mask on top keeps batched sequences of different lengths from attending to padding.
- Cross-attention, where the decoder’s queries attend over the encoder’s outputs. This is the part that does the alignment work in speech recognition: each output token learns which stretch of audio it should listen to.
Each attention sublayer is followed by a position-wise feed-forward network with a 4x expansion, and both encoder and decoder inputs get sinusoidal positional encodings, because attention on its own has no notion of order.
Part 1: A Decoder-Only Language Model
The first part stacks causal self-attention layers into a GPT-style language model over characters: a 35-token vocabulary, 256-dimensional embeddings, 1024-wide feed-forward layers and two decoder layers, about 1.6M parameters in total. It is trained with plain next-token cross-entropy. After training I generated text from it three ways (greedy, sampling and beam search), which was a good preview of how much the decoding strategy matters, a lesson that came back in Part 2.
Building this first meant the decoder for Part 2 was already tested: the speech decoder is the same causal stack with a cross-attention sublayer inserted into each layer.
Part 2: Transformer Speech Recognition
The second part transcribes LibriSpeech audio into text, trained on the 100-hour train-clean-100 split (28,539 utterances) and scored by character error rate (CER) on a Kaggle leaderboard.
Speech Front End
- Features: 80-dimensional Mel filterbanks per frame, with global mean-variance normalization.
- Time reduction: a strided convolution halves the number of frames before the encoder. Speech has far more frames than the transcript has tokens, and attention cost grows with the square of sequence length, so this is both a speed win and an easier alignment problem.
- SpecAugment: two frequency masks and two time masks per utterance during training, so the model cannot lean on any single band or moment of audio.
Model
| Setting | Value |
|---|---|
| Encoder layers | 3 (self-attention) |
| Decoder layers | 3 (causal self-attention + cross-attention) |
| Attention heads | 6 |
| Model dimension | 384 |
| Feed-forward dimension | 1536 |
| Output vocabulary | 5,000 BPE subword tokens |
| Parameters | about 30.7M |
The output projection shares its weights with the token embedding (weight tying), which saves parameters and kept training more stable.
Training
The loss is a weighted sum: 0.8 cross-entropy on the decoder’s predictions, with label smoothing of 0.1, plus 0.2 CTC loss on the encoder output. The point of the CTC term is to give the encoder its own alignment signal, pushing it toward monotonic, frame-level alignments early in training, before cross-attention has learned where to look. I trained for 64 epochs with AdamW, a 3-epoch linear warmup and cosine annealing, with lower learning rates for the attention and feed-forward weights than for the rest of the network. That took about 13 hours on a V100 on PSC Bridges-2.
Decoding
At inference the decoder generates one token at a time, conditioned on the audio through cross-attention. Greedy decoding takes the most likely token at every step, which is fast but cannot recover from an early mistake. Beam search keeps the best several partial transcripts alive and picks the best complete one at the end. I also softened the logits slightly and penalized repeated tokens, which stopped the occasional loop where the model repeats a word.
Results
| Decoding | CER |
|---|---|
| Greedy | about 14.3% |
| Beam width 5 | about 12.5% |
| Beam width 10 | about 11.6% |
Widening the beam past 10 gave almost nothing. The final submission scored about 12.0% CER on the public leaderboard and 12.6% on the private one.
The ablations that mattered most:
- Model size. At
d_model256 the model underfit, at about 18% CER. 384 was the sweet spot, and 512 was no better but slower to train. - Tokenization. Characters made sequences too long, and 10k BPE tokens left too many rare tokens with too little data. 5k BPE was the best balance.
- Time reduction. A strided convolution beat an LSTM-based reduction, and combining the two added parameters without helping.
- SpecAugment. Turning it off cost about 2 points of CER.
Most remaining errors were word boundaries (“NIGHTFALL” transcribed as “NIGHT FALL”), rare words and proper nouns, and very fast speech.
What I Took Away
The biggest lesson was how much of the final number came from outside the architecture. The same 30.7M-parameter model moved almost 3 points of CER between greedy and beam search, and about 2 more from augmentation. The auxiliary CTC loss was the other piece I came to appreciate: a small extra term that gives the encoder a direct training signal instead of relying entirely on gradients flowing back through cross-attention. Building the language model first, then reusing it as the speech decoder, also made it clear that a Transformer decoder does not care whether its context comes from text or from audio. Cross-attention is the only bridge.